Grafana Monitoring & Observability- From Beginner to Advanced – Live Training
( Learn Grafana Dashboards, Prometheus, Monitoring, Alerts & Observability through Hands-On Projects. )
This Grafana course is designed to help learners understand the fundamentals of monitoring, observability, and data visualization. Students will learn about Grafana architecture, its key features, installation, configuration, and user interface. The course introduces essential monitoring concepts and explains how Grafana helps visualize system performance and application health through interactive dashboards. The course also covers alerting and notification configuration, monitoring system performance, identifying potential issues, and troubleshooting common monitoring problems. Learners will be introduced to logs and distributed tracing concepts, along with tools such as Loki and Tempo, to understand how metrics, logs, and traces work together in modern observability environments.
By the end of the course, students will work on practical exercises and real-world monitoring scenarios to build confidence in using Grafana for production environments. This training is suitable for freshers, IT professionals, DevOps Engineers, Site Reliability Engineers (SREs), Cloud Engineers, and system administrators who want to develop practical monitoring and observability skills for their careers.The training covers integrating Grafana with Prometheus and exploring different visualization panels, dashboard variables, templates, and dashboard management techniques. Students will understand how to monitor infrastructure, applications, servers, and cloud environments effectively.
About the Instructor:
|
Pandit Sir is an experienced technical trainer with a strong passion for teaching monitoring, observability, and modern IT technologies. He focuses on helping students understand Grafana concepts from the fundamentals to advanced practical implementations, enabling them to build the skills required in real-world IT environments. His teaching methodology combines clear explanations, practical demonstrations, and industry-oriented examples to make complex technical concepts easier to understand. Students gain exposure to essential Grafana workflows and monitoring practices that can support their professional development in DevOps, Site Reliability Engineering (SRE), cloud operations, and observability engineering. Whether you are a fresher looking to build your technical foundation or a working professional aiming to enhance your monitoring and observability skills, Pandit Sir’s Grafana training is designed to help you develop practical knowledge and confidence for real-world projects. The training emphasizes understanding how monitoring tools help teams identify issues, analyze system performance, and maintain application reliability. |
Live Sessions Price:
Offer price after discount is 199 USD 129 61 USD Or USD13000 INR 9900 INR 5900 Rupees
OR
Free Demo Session:
For Participants in India: 26th October @ 9 PM – 10 PM (IST)
For Participants in the US: 26th October @ 11:30 AM – 12:30 PM (EST)
For Participants in U.K: 26th October @ 3:30 PM – 4:30 PM (BST)
Class Schedule:
For Participants in India: Monday to Friday @ 9 PM – 10 PM (IST)
For Participants in US: Monday to Friday @ 11:30 AM – 12:30 PM (EST)
For Participants in UK: Monday to Friday @ 3:30 PM – 4:30 PM (BST)
What student’s have to say about Pandit :
|
Pandit Sir explains Grafana concepts in a simple and easy-to-understand way. The practical demonstrations helped me understand dashboard creation and real-time monitoring –Lalitha The Grafana training was informative and practical. I learned about dashboards, data sources, Prometheus integration, and alert configuration through hands-on examples – Shanker As a beginner, I found the sessions very helpful. Pandit Sir explained each topic step by step and made complex monitoring concepts easier to understand – Cheery The course helped me understand how Grafana is used in real-world monitoring environments. The practical examples improved my knowledge of observability and system performance – Basha Pandit Sir’s teaching style is clear and engaging. He explains technical topics patiently and helps learners understand the concepts through practical demonstrations – Arjun It help me to understand concepts about grafana and their services. It goes directly to the point. – Samuel This training gave me a good foundation in Grafana monitoring and observability. I gained useful knowledge of dashboards, metrics, alerts, and monitoring applications! – Sree |
Who can enroll for this course?
- Freshers and recent graduates interested in IT careers
- DevOps Engineers who want to improve monitoring skills
- Software Developers interested in application performance monitoring
- Cloud Engineers who monitor cloud-based applications
- Site Reliability Engineers (SREs) who want to enhance observability skills
- Working Professionals looking to upgrade their Grafana and observability skills
What will I Learn by end of this course?
- Create interactive Grafana dashboards
- Understand Prometheus integration
- Monitor real-time system metrics
- Configure alerts and notifications
- Visualize logs using Grafana Loki
- Understand metrics, logs, and traces
- Monitor application and server performance
- Troubleshoot issues using Grafana dashboards
Salient Features:
- 35 Hours of Live Training along with recorded videos
- 1 Year access to the recorded videos
- Course Completion Certificate
Course syllabus:
Module 1 — Observability Fundamentals & Metrics
- Introduction to Observability and Monitoring
- Observability pillars: Metrics, Logs and Traces
- Monitoring vs Observability
- Key Observability concepts and terminology
- Application instrumentation fundamentals
- Structured application logging
- Prometheus fundamentals
- Metrics collection and querying with PromQL
- Grafana dashboards and visualization
Hands-on:
- Instrument and monitor a Python/FastAPI application
- Build application and infrastructure monitoring dashboards
Module 2 —Alerting with Prometheus & Grafana
- Observability-driven alerting
- Alert design and alert severity
- Prometheus alert rules
- Alert lifecycle: Inactive, Pending and Firing
- Grafana alerting concepts
Hands-on:
- Build application and latency alerts
Live Sessions Price:
Call or Whatsapp Kumar gupta @ +91- 9133190573
OR
Offer price after discount is 199 USD 129 61 USD Or USD13000 INR 9900 INR 5900 Rupees.
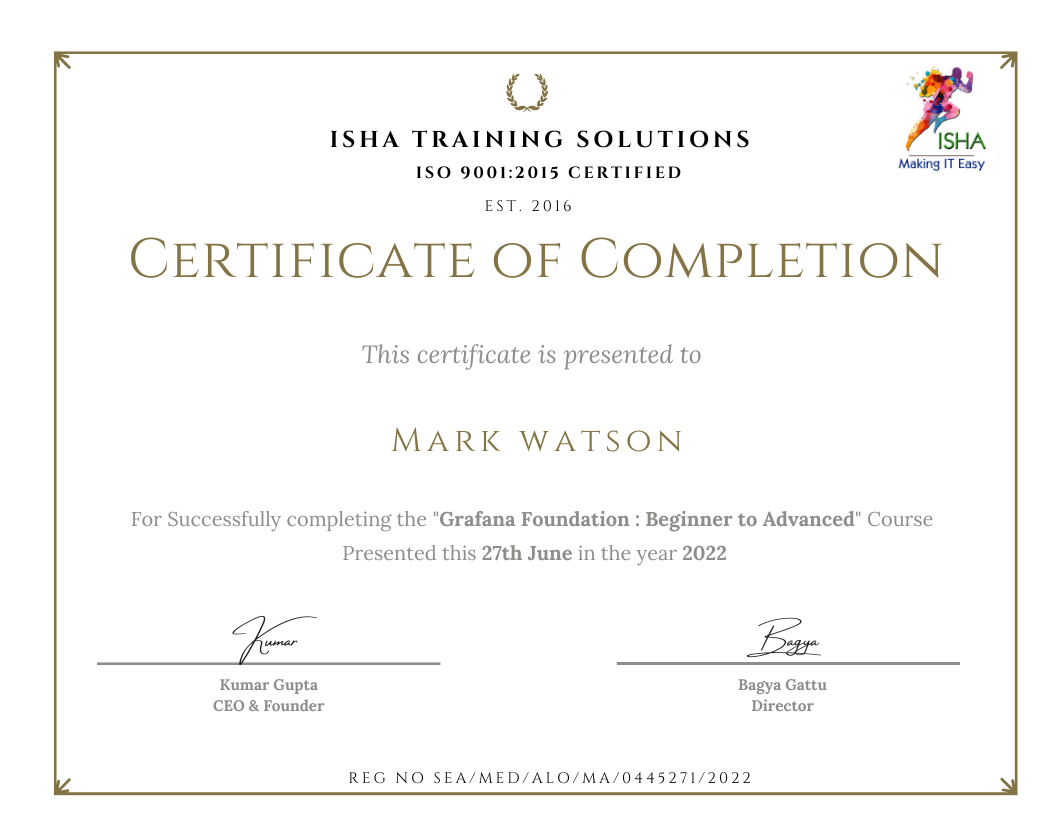
Sample Course Completion Certificate:
Your course completion certificate looks like this……
Course Features
- Lectures 85
- Quiz 0
- Duration 25 hours
- Skill level All levels
- Language English
- Students 0
- Assessments Yes
- 2 Sections
- 85 Lessons
- 25 Hours
- Module 1 — Observability Fundamentals & MetricsIntroduction to Observability and Monitoring56
- 1.1Introduction to Observability and Monitoring
- 1.2What observability is and how it helps understand system behaviour
- 1.3Role of observability in modern, containerised applications
- 1.4Observability pillars: Metrics, Logs and Traces
- 1.5Metrics: numeric measurements collected over time
- 1.6Logs: timestamped records of individual events
- 1.7Traces: the path of a single request through a system
- 1.8How the three pillars complement each other
- 1.9Monitoring vs Observability
- 1.10Key Observability concepts and terminology
- 1.11Reactive alerting vs exploratory analysis
- 1.12Monitoring known failure conditions vs investigating unknown issues
- 1.13How monitoring and observability work together
- 1.14Key Observability concepts and terminology
- 1.15Telemetry, signals and instrumentation
- 1.16Time series, samples and timestamps
- 1.17Labels and dimensions
- 1.18Scrape targets and collection intervals
- 1.19Application instrumentation fundamentals
- 1.20What instrumentation means and why applications need it
- 1.21Metric types: Counter, Gauge, Histogram and Summary
- 1.22Adding metrics to application code
- 1.23Exposing metrics through a /metrics endpoint
- 1.24Structured application logging
- 1.25Structured vs plain-text logs
- 1.26Key-value and JSON log formats
- 1.27Log levels: DEBUG, INFO, WARNING, ERROR
- 1.28Consistent log fields: timestamp, level, message, service
- 1.29Prometheus fundamentals
- 1.30Prometheus architecture: server, time-series database and targets
- 1.31Pull-based scraping model
- 1.32Prometheus configuration (prometheus.yml) and scrape jobs
- 1.33Prometheus web UI, targets page and expression browser
- 1.34Metrics collection and querying with PromQL
- 1.35Configuring scrape targets and verifying collection
- 1.36Instant vectors and range vectors
- 1.37Metric selectors and label matchers
- 1.38Functions: rate(), increase() and histogram_quantile()
- 1.39Aggregations: sum, avg, max and grouping with by / without
- 1.40Grafana dashboards and visualization
- 1.41Grafana overview and interface
- 1.42Connecting Prometheus as a data source
- 1.43Panel types: Time series, Stat, Gauge and Table
- 1.44Dashboard variables for dynamic filtering
- 1.45Organising, saving and sharing dashboards
- 1.46Instrument and monitor a Python/FastAPI application
- 1.47Hands-on:
- 1.48Run the FastAPI application, Prometheus and Grafana with Docker Compose
- 1.49Add request count, latency and error metrics to the application
- 1.50Expose the /metrics endpoint and configure Prometheus to scrape it
- 1.51Verify collected metrics in the Prometheus UI using PromQL
- 1.52Build application and infrastructure monitoring dashboards
- 1.53Application dashboard: request rate, error rate and latency
- 1.54Infrastructure dashboard: CPU, memory and container resource usage
- 1.55Write PromQL queries for each panel
- 1.56Add variables and organise panels into a usable dashboard
- Module 2 — Alerting with Prometheus & GrafanaObservability-driven alerting29
- 2.1Purpose of alerting in an observability setup
- 2.2Alerting on user-facing symptoms vs internal causes
- 2.3Avoiding alert fatigue and noisy alerts
- 2.4Alert design and alert severity
- 2.5Designing actionable alerts
- 2.6Choosing thresholds and evaluation durations
- 2.7Severity levels: Critical, Warning and Info
- 2.8Using labels and annotations to add context
- 2.9Prometheus alert rules
- 2.10Alert rule file structure and rule groups
- 2.11Rule fields: expr, for, labels and annotations
- 2.12Loading alert rules into Prometheus
- 2.13Viewing alerts on the Prometheus Alerts page
- 2.14Alert lifecycle: Inactive, Pending and Firing
- 2.15Inactive: condition not met
- 2.16Pending: condition met, waiting for the ‘for’ duration
- 2.17Firing: condition held for the full duration
- 2.18How alerts return to Inactive when resolved
- 2.19Grafana alerting concepts
- 2.20Grafana alert rules and evaluation groups
- 2.21Alert states in the Grafana interface
- 2.22Contact points
- 2.23Notification policies
- 2.24Hands-on:
- 2.25Build application and latency alerts
- 2.26Build application and latency alerts
- 2.27Create a high latency alert using histogram_quantile()
- 2.28Generate load and failures to watch alerts move from Pending to Firing
- 2.29Create a Grafana alert rule from a dashboard query